SSO Agency · November 20, 2026
Secure AI Deployment Guide for Growth Leaders
A sales team pasting customer conversations into a public chatbot, an internal assistant with access to every shared drive, and a workflow that can update CRM records without review can all begin as seemingly useful experiments. They can also create avoidable exposure in a matter of days. A secure AI deployment guide is not a document to write after launch. It is the set of business and engineering decisions that determines whether an AI initiative creates operational leverage or introduces a new source of risk.
For growth-stage companies, the goal is rarely to build a research project. The goal is to remove manual bottlenecks, improve decisions, support customers faster, or give teams a better interface to fragmented information. Security has to support that goal, not bury it under process. The right approach is proportionate: apply stronger controls where data is sensitive, actions have consequences, and a failure would affect customers, revenue, or trust.
Secure AI deployment starts with the business boundary
Many AI projects become difficult because the team starts with a model choice instead of a defined operating problem. Before evaluating providers, prompts, or frameworks, establish what the system is allowed to do and what it must never do.
A useful starting point is a plain-language statement: who will use the system, what decision or task it supports, which systems it can access, and what happens after it produces an answer. An internal knowledge assistant that summarizes approved policies has a different risk profile from an agent that issues refunds, changes subscription plans, or drafts regulated customer communications.
This distinction matters because AI output is probabilistic. A well-designed system can be accurate and useful without being treated as infallible. The more directly an output affects a customer, financial record, production environment, or legal obligation, the more review and control it requires.
Define the use case before granting access
Start narrow enough to measure. Rather than giving an assistant broad access to company data, identify the specific workflow creating friction. It might be answering repetitive internal questions from a controlled policy library, classifying inbound requests, extracting structured information from approved documents, or preparing a first draft for human review.
Then define the boundary in practical terms. What information is in scope? Which users can use the tool? Can it only read data, or can it take action? Does a person review every result, or only exceptions? These choices turn an abstract security conversation into an execution roadmap.
Narrow scope is not a compromise on ambition. It is how teams prove value, learn where the workflow breaks, and expand with confidence. Broad access is easy to request and expensive to unwind.
Classify the data, not just the application
Security requirements should follow the data and the consequence of misuse. A marketing content assistant using public product information needs different controls than a support copilot handling account details or an operations workflow processing employee records.
Create a clear inventory of the data the AI system may receive. Include source documents, prompts, user-uploaded files, retrieved knowledge, conversation history, logs, and generated outputs. Teams often account for the primary database while overlooking debugging tools, analytics platforms, or third-party connectors that retain copies of sensitive information.
For each category, decide whether it is permitted, restricted, masked, or excluded. Personal data, credentials, financial information, confidential contracts, and proprietary source code deserve explicit handling rules. If a workflow does not need a field to complete its job, do not send it. Data minimization reduces both technical and operational risk.
Build security controls into the AI architecture
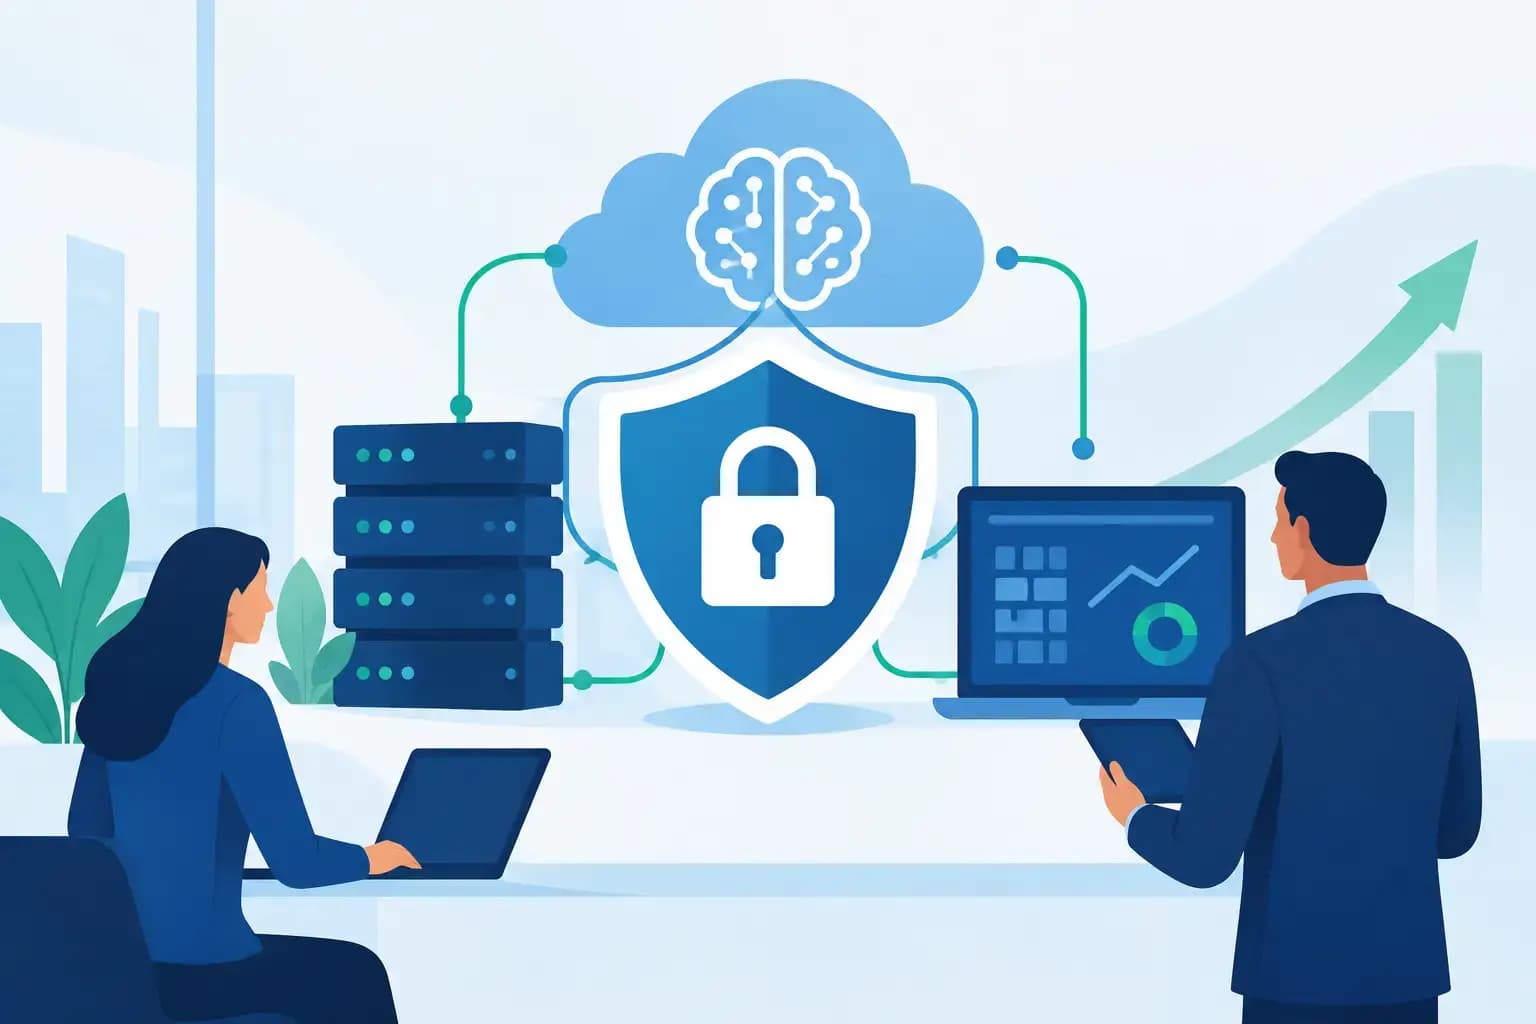
A secure AI system is more than a secure model provider. The application layer, identity setup, integrations, storage, and monitoring all matter. Most avoidable failures occur in the connections around the model rather than in the model itself.
The architecture should enforce least-privilege access. An assistant that helps a support representative find relevant documentation should not inherit administrative access to the CRM. An automation that drafts a renewal email should not be able to send it without approved workflow controls.
The following controls are usually worth establishing before a system moves beyond a contained pilot:
- Identity and role-based access: Tie usage to authenticated users and restrict features, data sources, and actions by role. Shared credentials make investigations and accountability far harder.
- Scoped integrations: Use narrowly permissioned service accounts and APIs. Separate read access from write access, and limit access to the records or fields the workflow actually needs.
- Secrets management: Keep API keys, tokens, and credentials out of prompts, code repositories, and client-side applications. Rotate them on a defined schedule and revoke access quickly when roles change.
- Encryption and retention controls: Protect data in transit and at rest, then define how long prompts, files, outputs, and logs are retained. Retaining everything indefinitely is rarely a sensible default.
- Audit logging and alerting: Record meaningful events such as access requests, data retrieval, tool calls, approval decisions, and failures. Logs should help an operator answer what happened, who initiated it, and what data or action was involved.
These controls need to fit the workflow. A small internal tool does not require the same architecture as a customer-facing product handling sensitive information at scale. But every production system needs traceability, controlled access, and a way to contain failure.
Treat prompt injection as an application security issue
Prompt injection is not only a prompt-writing problem. It occurs when untrusted content, such as a webpage, uploaded file, email, or support ticket, attempts to influence the system's instructions or trigger unintended actions.
Do not rely on a system prompt alone to prevent this. Separate trusted instructions from untrusted content, constrain which tools the model can call, validate tool inputs outside the model, and require confirmation before consequential actions. If an AI system can write to a business system, its permissions and validations should be as deliberate as those of any other production integration.
Testing should include adversarial inputs, not just happy paths. Ask what happens when a document contains misleading instructions, a user requests prohibited information, or an external source attempts to change the system's priorities. A system that performs well in a demo can still behave unpredictably in a live workflow.
Keep humans where judgment carries the risk
Human review is often described as a temporary measure until automation matures. That framing misses the point. In many workflows, human judgment is the control that makes automation commercially usable.
For low-consequence tasks, such as categorizing inbound messages or preparing internal summaries, automation can operate with limited oversight and sampled quality checks. For tasks involving external communication, customer eligibility, payments, employment decisions, or production changes, use approval gates and clear escalation paths.
The right level of review depends on the cost of an incorrect action, the reversibility of that action, and the quality of available source data. A mistaken draft is easy to correct. A mistaken account change or exposed record may not be. Design the workflow around that difference.
Teams should also define ownership. Someone needs responsibility for model behavior, data access, workflow performance, incident response, and change approval. Without named owners, AI systems can become orphaned automations that continue operating after the original business context has changed.
Test in production-like conditions before scaling
A pilot is valuable only when it tests the conditions that matter. Use realistic data with appropriate protections, representative users, edge cases, and the actual systems the workflow will touch. Measure more than output quality. Track how often users override results, where requests fail, whether approvals slow work unnecessarily, and whether the automation creates new manual cleanup.
Establish success and stop criteria before rollout. Success might mean reducing the time required for a defined internal task while maintaining an acceptable review rate. Stop criteria might include repeated policy violations, unreliable source retrieval, unexpected data exposure, or an error pattern with material business consequences.
This is also where cost discipline matters. Model usage, retrieval, storage, observability, and integration calls all affect operating cost. A system that performs well at low volume may need architectural changes before it serves a larger team or customer base. Capacity planning and cost controls are part of secure, maintainable deployment.
Make governance practical enough to use
AI governance does not need to become a committee that blocks delivery. It should provide a lightweight way to approve use cases, assess risk, document decisions, and revisit systems as they change.
For each production AI workflow, maintain a short record covering its purpose, owner, allowed data, connected systems, permitted actions, evaluation method, and escalation path. Review it when the model changes, the tool gains a new integration, the data source expands, or the workflow takes on a higher-impact task.
This documentation has commercial value beyond compliance. It makes technical decisions understandable to executives, supports customer and investor questions, and reduces dependency on the individual who originally built the system. It also makes it easier to identify where an AI project should remain a pilot and where it is ready to become core operating infrastructure.
At SSO Agency, we approach AI work as an operating and architecture decision, not a feature race. The strongest deployments connect a clear business case to disciplined access controls, tested workflows, and an implementation plan the internal team can maintain.
The most useful next step is usually not choosing a model. It is selecting one workflow where better speed or consistency would matter, mapping the data and decisions involved, and designing the smallest controlled version that can prove its value. That is how companies move from AI experimentation to systems they can trust to run.