SSO Agency · September 3, 2026
How to Map Software Dependencies Without Guesswork
A release fails because a service no one considered still relies on an old database table. A vendor outage blocks customer onboarding because a background workflow calls its API. A small infrastructure change creates a security exposure in a separate environment. These are not isolated engineering mistakes. They are the commercial cost of hidden dependencies.
Knowing how to map software dependencies gives technical and business leaders a clearer view of what must change together, what could break, and where risk is concentrated. Done well, dependency mapping becomes a decision tool for modernization, product expansion, due diligence, incident planning, and day-to-day delivery.
What a software dependency map should show
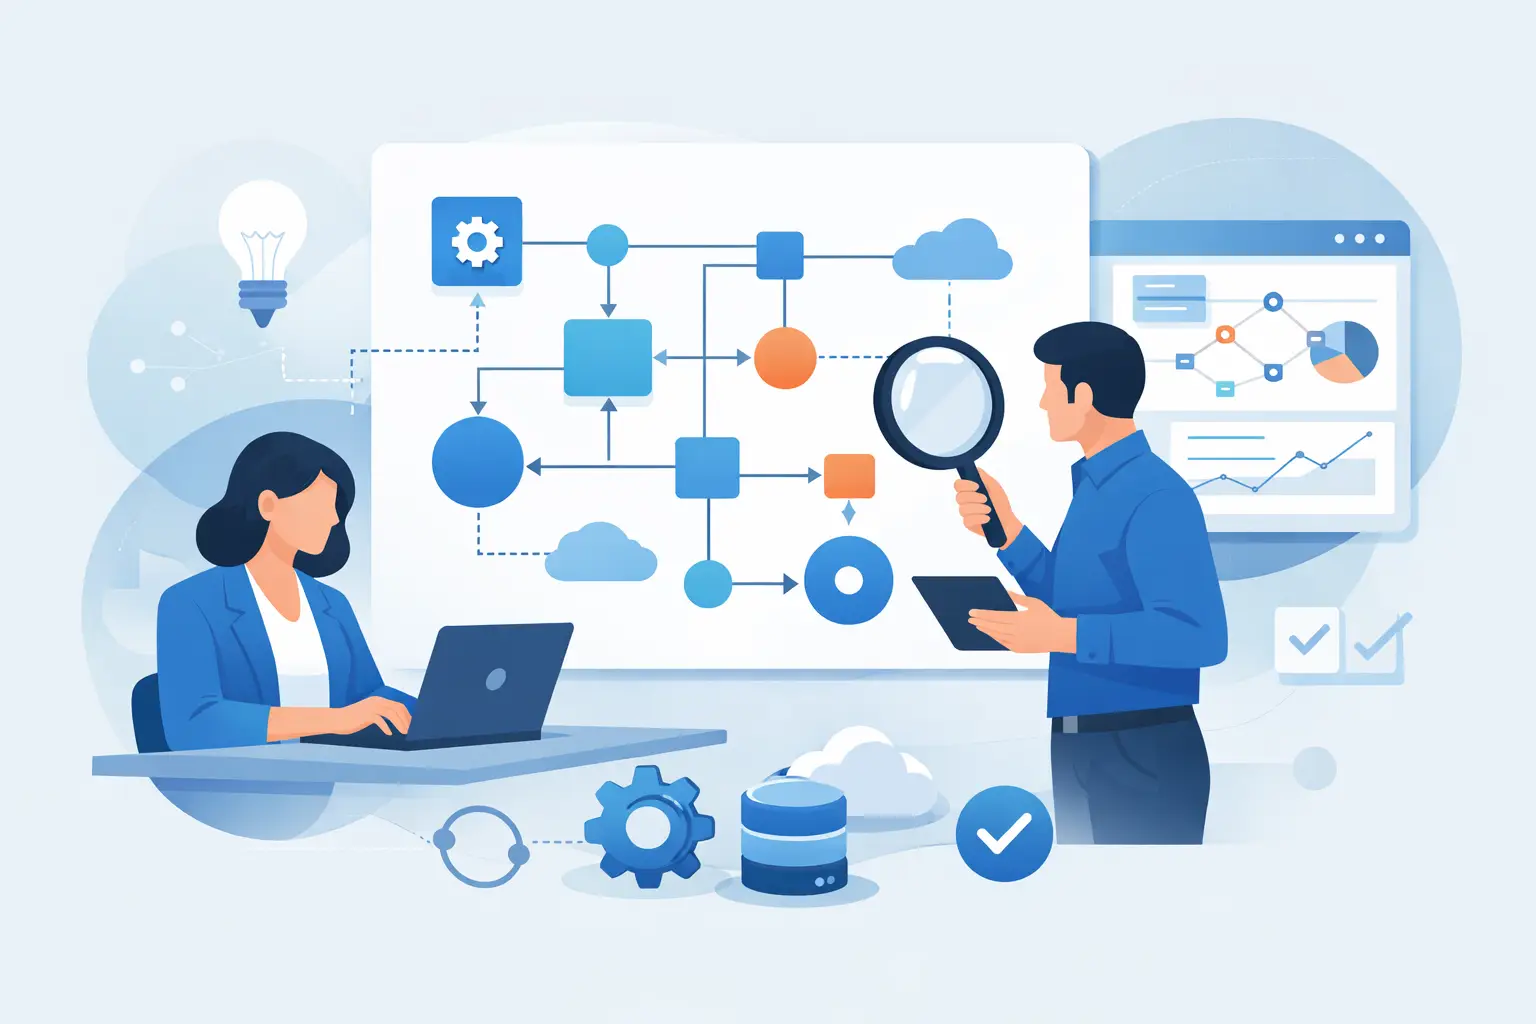
A dependency map is a living model of the relationships required for a product or operational workflow to function. It should show more than which code package imports another package. For an executive team, the useful question is: if we change, remove, acquire, or lose this component, what business capability is affected?
A useful map connects four layers. The application layer includes services, repositories, APIs, jobs, libraries, and shared components. The infrastructure layer covers cloud accounts, environments, databases, queues, storage, networks, and identity systems. The data layer shows critical data stores, data flows, schemas, and reporting pipelines. The external layer captures SaaS tools, payment processors, communications providers, analytics platforms, and other vendors.
The map should also identify ownership and criticality. A dependency without an accountable owner is harder to change safely. A dependency supporting revenue, compliance, customer access, or core operations deserves more scrutiny than an internal convenience tool.
This does not mean every minor utility needs a diagram. The right level of detail depends on the decision at hand. A post-MVP rebuild may need a broad architectural view first. A planned database migration needs a much deeper view of consumers, jobs, reports, integrations, and recovery paths.
Start with a business capability, not a tool inventory
Many teams begin by exporting a list of cloud resources or scanning repositories. Those activities are useful, but they can produce a large inventory without explaining what matters.
Start with the business capability you need to protect or change. For example: customer signup, order fulfillment, client reporting, invoice collection, or agency campaign provisioning. Define the triggering event, the expected outcome, the systems involved, and the team responsible for the workflow.
A customer signup flow may begin in a web application, pass through an identity provider, write data to a customer database, trigger a CRM update, notify a sales team, and feed an analytics event. That sequence reveals both technical relationships and operational consequences. If the CRM integration fails silently, sales follow-up slows. If identity is unavailable, revenue capture may stop entirely.
This approach keeps the mapping effort tied to a real outcome. It also makes it easier to prioritize investment. Not every dependency deserves the same remediation budget.
How to map software dependencies in seven steps
1. Set the scope and the decision
Be explicit about why the map is being created. Common triggers include replacing a legacy system, preparing for a fundraising technical review, separating a product from a parent platform, assessing acquisition risk, or reducing incident frequency.
Define the boundary as well. Include production first unless the change specifically affects development, test, or staging environments. State whether the map covers one workflow, one product domain, or the full technology estate. A clear scope prevents the work from expanding into an expensive documentation exercise.
2. Build an initial component inventory
Gather the components that support the selected capability. Start with architecture diagrams, source repositories, deployment configurations, cloud accounts, API gateways, identity settings, database instances, and vendor contracts. Then validate that inventory with the engineers and operators who work with the systems.
Documentation is often incomplete, especially in growth-stage companies. Treat it as a hypothesis, not evidence. The most valuable findings frequently come from comparing documented architecture with what is actually deployed and used.
For every component, record a plain-language purpose, owner, environment, technology, and lifecycle status. Is it actively maintained, stable but aging, scheduled for replacement, or effectively abandoned? This context turns a technical inventory into an execution roadmap.
3. Identify the relationships, not just the components
Next, map the connections between components. Capture the direction of the relationship and the type of dependency. A service might call an API synchronously, publish an event to a queue, read from a shared database, depend on a deployment pipeline, or authenticate through a central identity provider.
The distinction matters. A synchronous API call can directly affect user experience. An asynchronous event may create delayed operational work instead. A shared database can create hidden coupling that makes seemingly independent releases risky.
For each relationship, document what moves across it: requests, events, files, credentials, configuration, or data. Record the protocol or mechanism, such as REST, webhook, message queue, batch export, or direct database access. Also note what happens when the connection fails. Does the process retry, degrade gracefully, alert someone, or fail without visibility?
4. Trace critical data and access paths
Data dependencies are frequently underestimated. A system can appear separate at the service level while relying on the same customer identifiers, permissions model, data pipeline, or reporting tables.
Identify where sensitive and business-critical data originates, where it is transformed, and where it is stored. Include personal data, payment-related information, contracts, product usage events, and operational records. Then map who and what can access each store, including service accounts, administrative users, automation tools, and third-party integrations.
This step supports security decisions as well as delivery planning. It can expose excessive permissions, uncontrolled exports, unsupported data stores, and integrations that have access far beyond their intended purpose.
5. Add criticality, failure impact, and change risk
A dependency map becomes useful when it shows consequences. Classify each component and relationship according to business criticality, operational impact, security sensitivity, and ease of replacement.
Ask direct questions. If this service is unavailable for four hours, can customers still transact? If this vendor changes pricing or terms, what is the cost to switch? If this database schema changes, which reports, automations, and client-facing features could fail? If one senior engineer is unavailable, does the team understand how to operate the component?
Avoid false precision. A simple high, medium, or low rating is often enough to expose priorities. What matters is that the rating is based on evidence and linked to a clear mitigation action.
6. Validate the map against production behavior
Static analysis and architecture tools can identify code-level imports, service calls, and infrastructure references. They cannot reliably explain manual workarounds, undocumented vendor use, emergency scripts, or the operational habits that keep a fragile process running.
Validate the map through short interviews with engineering, product, operations, security, and customer-facing teams. Compare it with logs, monitoring traces, incident records, deployment history, and access reviews. The goal is not to prove that a diagram is perfect. It is to find the gaps between assumed behavior and real behavior.
This is where organizations often uncover dependencies on spreadsheets, shared inboxes, individual credentials, manual exports, or a single person’s knowledge. Those are operational dependencies, and they can be just as disruptive as a failing API.
7. Turn findings into a prioritized plan
The deliverable should not be a diagram that becomes outdated after one presentation. Use the map to make decisions: retire duplicate tools, decouple a shared database, add monitoring to a critical integration, replace an unsupported library, document a recovery procedure, or assign an owner to an orphaned system.
Separate immediate risk reduction from longer-term architecture work. For example, adding alerts and tested backups may reduce near-term exposure while a larger migration is planned. Rebuilding every legacy dependency immediately is rarely practical. The right sequence depends on customer impact, revenue exposure, security obligations, available capacity, and the cost of delay.
Choose tools based on evidence and maintenance effort
The best toolset depends on the estate. Application performance monitoring and distributed tracing can expose live service interactions. Cloud inventory tools help identify infrastructure relationships. Dependency scanners reveal vulnerable packages and outdated libraries. Data catalogs can clarify lineage and ownership. Diagramming tools provide a shared view for executives and delivery teams.
No single platform will map every dependency accurately. A SaaS inventory tool may miss custom integrations. A code scanner may miss workflow automation configured outside the repository. An infrastructure graph may not show why a connection matters to a customer journey.
Use automation to gather evidence, then have senior technical people interpret it. The aim is not to create an impressive visual. It is to reduce technical and operational risk before a change, investment, or growth initiative exposes it.
Keep the map current without creating overhead
Dependency maps decay when they are treated as one-time architecture artifacts. Build updates into existing delivery controls instead. Require teams to review affected dependencies during meaningful design changes, vendor additions, infrastructure migrations, and production incidents. Keep ownership and criticality visible in the same place teams use to plan work.
For smaller companies, quarterly reviews of the highest-risk workflows may be sufficient. For a platform making frequent releases or handling regulated data, updates should be part of the change process. The discipline should match the pace and consequences of change.
A clear dependency map does not eliminate complexity. It gives leaders and delivery teams a shared way to see it, challenge assumptions, and make the next change with fewer surprises. That is a stronger foundation for shipping quickly without treating preventable risk as the cost of growth.